
Xiaomi MiMo UltraSpeed: A Trillion-Parameter Model Running at 1000 tokens/s
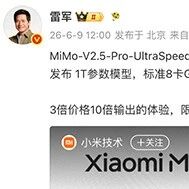
Xiaomi's MiMo-V2.5-Pro UltraSpeed delivers 1000 tokens/s on a trillion-parameter model running on generic 8-GPU hardware — and it's the full-strength Pro version, not a dumbed-down Flash variant. The API is live and taking applications.
Xiaomi MiMo UltraSpeed: A Trillion-Parameter Model Running at 1000 tokens/s
Xiaomi's MiMo-V2.5-Pro UltraSpeed delivers 1000 tokens/s on a trillion-parameter model running on generic 8-GPU hardware — and it's the full-strength Pro version, not a dumbed-down Flash variant. The API is live and taking applications.
Xiaomi's MiMo team and the inference systems team TileRT jointly announced that MiMo-V2.5-Pro's UltraSpeed mode has pushed a trillion-parameter (1T) flagship model past the 1000 tokens/s output mark for the first time. More importantly, this isn't a dumbed-down Flash variant — it's the full-strength Pro version.
That means roughly a 10x speedup while maintaining top-tier intelligence.
Real-World Speed
Take a complex visual dashboard generation task as an example:
- UltraSpeed version: done in 13 seconds
- Standard version: 6 minutes 15 seconds
- Up to a 28x speedup for the same quality of output
In hands-on testing, peak speed even reached 1426 tokens/s, outputting 25624 tokens in 32 seconds and generating 1000 lines of code. A Snake game takes 10 seconds to generate, and a macOS system UI can be reproduced in 1 minute.
How It Works
Unlike dedicated-hardware approaches such as Cerebras' wafer-scale integration or Groq's custom pure on-chip SRAM chips, Xiaomi pulled this off on generic GPUs — a single standard 8-GPU node.
The core technology has three parts:
1. FP4 quantization: a dramatic slim-down without losing accuracy
- Only the MoE experts get FP4 quantization; other modules keep their original precision
- Through FP4 quantization-aware training (QAT), the model's overall capability stays essentially on par with the original
- Model size and memory-access overhead are both dramatically reduced
2. DFlash speculative decoding: confirming multiple text segments in one go
- Uses a block-level masked parallel prediction method, removing the serial constraint of autoregressive drafting
- In coding scenarios the average acceptance length reaches 6.30, with 6-7 of every 8 drafted tokens accepted per verification round
- The draft model uses sliding-window attention (SWA), making per-prediction compute constant
3. TileRT custom compiled kernels
- Resident kernel engine: the compute pipeline lives inside the GPU and keeps flowing continuously
- Heterogeneous pipeline collaboration: communication, data movement, and tensor compute are finely decomposed at the tile level
- Microsecond-level hardware-software convergence: purpose-built for FP4 mixed quantization and DFlash
Pricing and API
The API is live with a limited-time trial price:
- Priced at 3x MiMo-V2.5-Pro, in exchange for roughly a 10x output speedup
- Based on MiMo-V2.5-Pro pricing, that works out to roughly ¥18 per million output tokens
- API trial only; Token Plan not supported yet
- Applications are open June 9 through June 23; approved users get two weeks of free limited-time Chat access
Why Speed Matters in Practice
The speedup isn't just "faster" — it unlocks entirely new usage patterns:
- Agent scenarios: if you estimate a task takes one minute, you'll watch it through to the end. If it takes five minutes, you'll probably go do something else and waste time coming back. A 10x speedup directly changes your working rhythm
- Sub-Agent concurrency: spin up one or two hundred sub-agents at once; with a 10x speedup and zero loss in model capability, the difference in experience is dramatic
- Real-time decision loops: trillion-parameter models can plug into time-critical scenarios like high-frequency quantitative trading signal generation and instant fraud-detection interception
How to Apply
- API application: https://platform.xiaomimimo.com/ultraspeed
- Chat trial: https://ultraspeed.xiaomimimo.com
- Open-source weights (FP4-DFlash): https://huggingface.co/XiaomiMiMo/MiMo-V2.5-Pro-FP4-DFlash
Tip: The current high acceptance rates are still concentrated mainly in structured tasks like coding; general conversation still has room for optimization. Inference capacity is tight, so broad commercial availability will take time.
Toolin Editorial Team
Categories
Related articles
Claude Code Verification Loops: 4 Built-in Skills That Make AI Self-Check Code Before Delivery
Build a verification layer with Claude Code's four built-in skills — /code-review, /simplify, /verify, and /design — so the AI self-checks its code before handing it over.
Logi Options+: Turn an Old Mouse into an AI Workflow Controller (Zero-Cost Setup)
Use Logitech's free official driver Logi Options+ — Smart Actions, Actions Ring, and per-app settings — to mod any Logitech mouse into a Vibe Mouse, a DIY alternative to the $230 Codex Micro keyboard.
Loom: An Engineering State Layer for Coding Agents That Cures Long-Task Local Amnesia
The open-source tool Loom gives coding agents like Claude Code / Codex an independent, structured engineering state layer, enabling long-task auto-checkpointing and zero-cost multi-agent handoff.
Jetson-PI: Peking University Open-Sources Real-Time On-Device VLA Control, 8.66× Higher Control Frequency on Jetson Orin
Peking University, AIRS, and PrimeBot open-source Jetson-PI (Apache-2.0): FAAC asynchronous inference + confidence scheduling + a llama.cpp engine lift π0.5 on Jetson Orin from 0.70Hz to 6.06Hz, with no loss in accuracy.
JiuwenSwarm: A Huawei-Backed Open-Source Multi-Agent Unified Workbench Where Humans Join the Agent Team
openJiuwen open-sources JiuwenSwarm (Apache-2.0), merging office / Code / entertainment work into a unified workbench and launching HITS, a new human-agent collaboration paradigm — installable with a single pip line.
OpenWorker: Andrew Ng's Open-Source Desktop AI Coworker That Ships Finished Work
Andrew Ng open-sources OpenWorker (MIT), a local-first, model-agnostic desktop agent connecting to 25+ tools, turning "prepare a customer brief" into a finished document you can actually open.