Arena AI
Crowdsourced LLM evaluation and leaderboard platform driven by human blind votes
Tool details
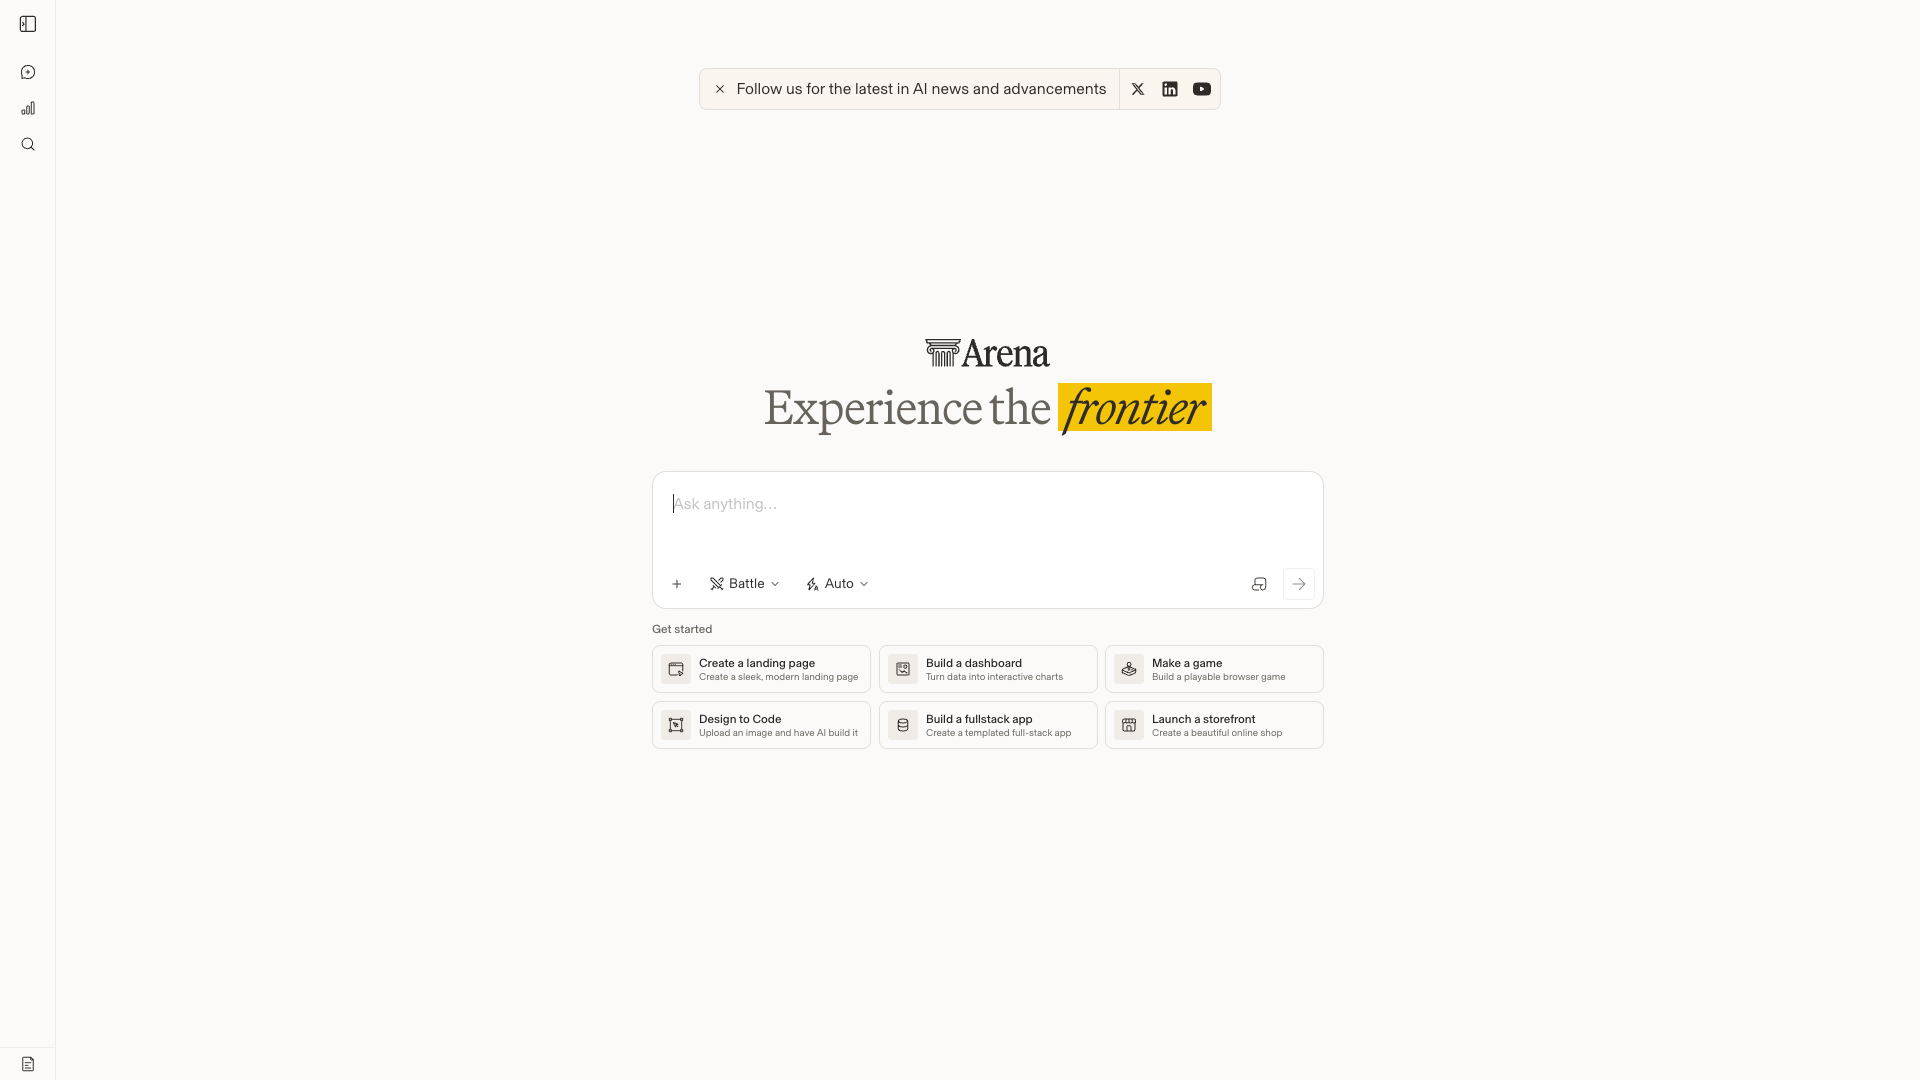
Arena AI is a crowdsourced LLM evaluation and leaderboard platform originating from UC Berkeley, formerly Chatbot Arena / LMArena, ranking frontier models by human blind-vote preference. The submitted name "Code Arena" is in fact its code evaluation sub-product (arena.ai/code); the listing name follows the real brand, Arena AI.
Core capabilities
- Human blind-vote battles: the same prompt is answered by two anonymous models, and the user blind-picks the better one before identities are revealed
- Multimodal leaderboards: seven Arenas covering text/code/vision/image/video/search/agent
- Code Arena: two models build runnable web apps in parallel sandboxes; voting requires previewing both first, with three-aspect scoring for functionality/usability/fidelity
- Fullstack evaluation: supports PostgreSQL, authentication, third-party APIs, and one-click deployment to Vercel
- Ranking methodology: Bradley-Terry plus Style Control to remove writing-style bonuses, with the open-source arena-rank package published
- Cost-performance Pareto: shows performance against cost per task
Use cases Model selection and shortlisting by developer/engineering teams, AI researchers, pre-release testing by model vendors, procurement support for enterprises, and ordinary users who want to try frontier models for free; better used as a screening starting point than a production basis.
Unique strengths Complementary to, not a replacement for, Artificial Analysis (automated metrics + price and speed); compared with the discontinued HF Open LLM Leaderboard and SWE-bench, the differentiation is large-scale human blind-vote preference + fully interactive apps + cost-performance Pareto. Note: it shares only the name "Arena" with Design Arena (designarena.ai) and Alpha Arena (nof1.ai); the companies and tracks differ.
Editorial review UC Berkeley lineage, 5M+ monthly active users, 82M+ votes, 400+ models; a general reference cited by media and during model release seasons. The consumer side is entirely free and voting requires no login; /pricing tested as a soft 404. Points deducted for leaderboards being gameable (the Llama 4 private variant incident) and for "preference ≠ correctness"; best used as a shortlist screener. Rating 4/5.
Pricing
Freemium$0 (Free)Public arena/leaderboards/voting free; no personal paid subscription
Custom quote, usage-based billing; private evaluations and custom benchmark suites
Additional notes
The consumer side is entirely free, and this does not constitute a free commitment on the enterprise side. Two third-party secondhand reports of enterprise pricing conflict with each other (starting around $2,000/month vs. $50,000–$500,000 annually, neither official, no currency conversion); they are listed side by side as-is, and the official sales quote should prevail. Note: voting and conversation data may be de-identified and then published to research datasets or shared with model vendors, so the official guidance is not to enter sensitive information.
FAQ
User reviews
User Reviews
No reviews yet
No one has reviewed this tool yet