Fireworks AI
Inference and training platform for open models
Tool details
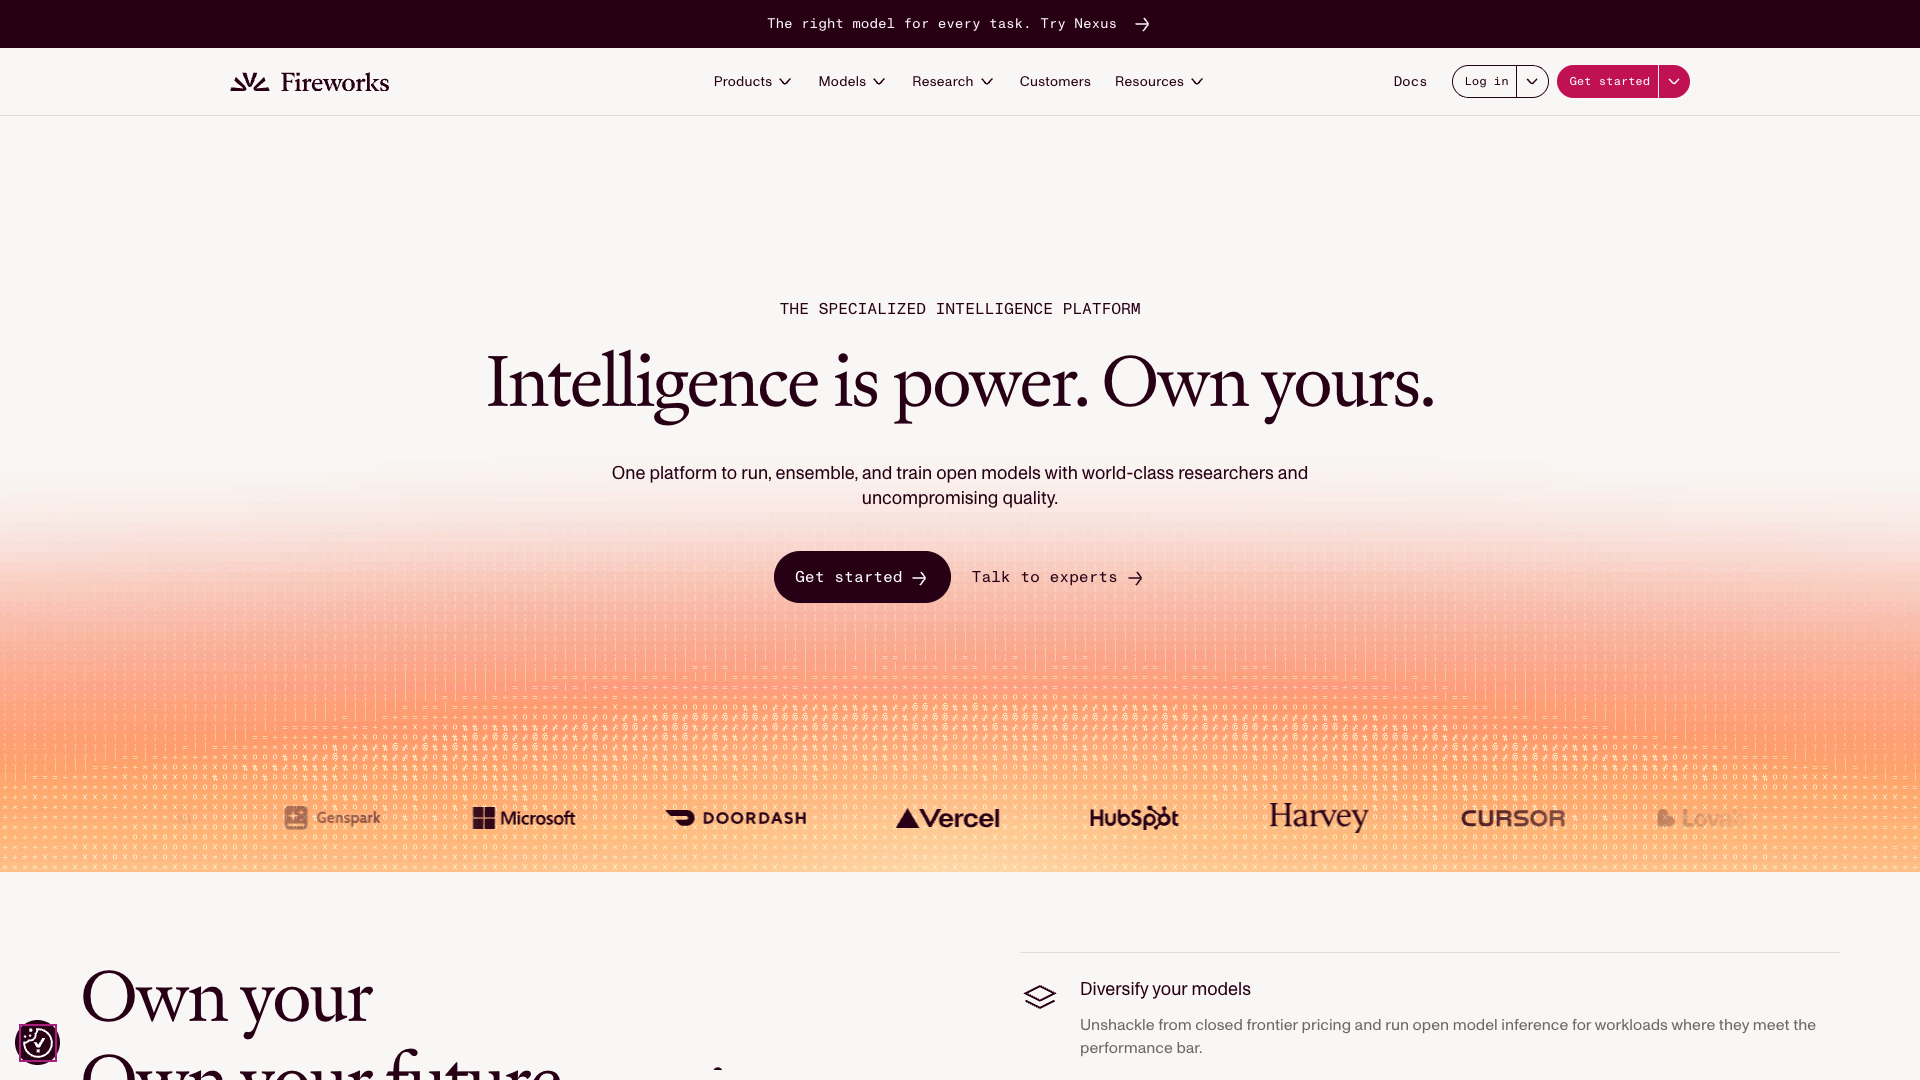
Fireworks AI is an inference and training platform that turns open models into production services, built around one idea: own your specialized intelligence. It is aimed at engineering teams wiring models into real systems, not at people looking for a chat box.
Core capabilities
- Pay-per-token inference: one endpoint serves Kimi, DeepSeek, GLM, Qwen and other open models, priced per token from $0.05/1M input
- Model ensembling: routes each turn across several models, sending routine work to cheap ones and reserving premium models for the turns that matter
- Managed training: upload a dataset and run SFT, DPO or LoRA fine-tuning without standing up a training cluster
- Reserved throughput and private deployment: reserved capacity comes with an SLA, and Sovereign keeps inference inside your own cloud account or data center
- Performance engineering: the vendor claims up to 4x the throughput of providers wrapping vLLM, with cache hit rates up to 99.6% on long runs
- Nexus workspace: a co-work surface for individuals and teams from $8 per month
Where it fits Backend teams shipping open models, agent and RAG projects squeezing token cost, industry teams that need domain fine-tuning, and enterprises with data residency requirements.
Why it stands out This is not an API reseller: Fireworks rewrites kernels, does its own quantization and caching, and publishes quality checks against lab reference implementations. Its catalog spans general models like Kimi and GLM plus open weights such as Nemotron and gpt-oss, tying inference, ensembling and training into one control plane.
Editor's take A good fit for teams with known volume that treat cost and quality as engineering metrics; individuals will find it too infrastructural. There is no standing free tier, so validate demand on someone else's free credits first. For procurement, run pay-as-you-go for a few weeks before committing to a reserved contract.
Pricing
Subscription$0.05/1M input tokensBilled per token; priority and batch modes switch per request
Contract required, includes a throughput SLA and availability commitment
Private preview; inference runs in your own cloud or data center
Co-work surface for individual developers, with an open-model allowance
Priced per seat, with member, seat and billing management
Upload a dataset in the UI and run LoRA fine-tuning
Run your own training loop, billed by GPU time
Idle deployments scale to zero after 1 hour by default
Additional notes
No standing free allowance; pay-as-you-go runs on prepaid credits, and limited-time offers follow in-site announcements.
FAQ
User reviews
User Reviews
No reviews yet
No one has reviewed this tool yet