SaladCloud
A distributed consumer GPU cloud that is up to 90% cheaper
Tool details
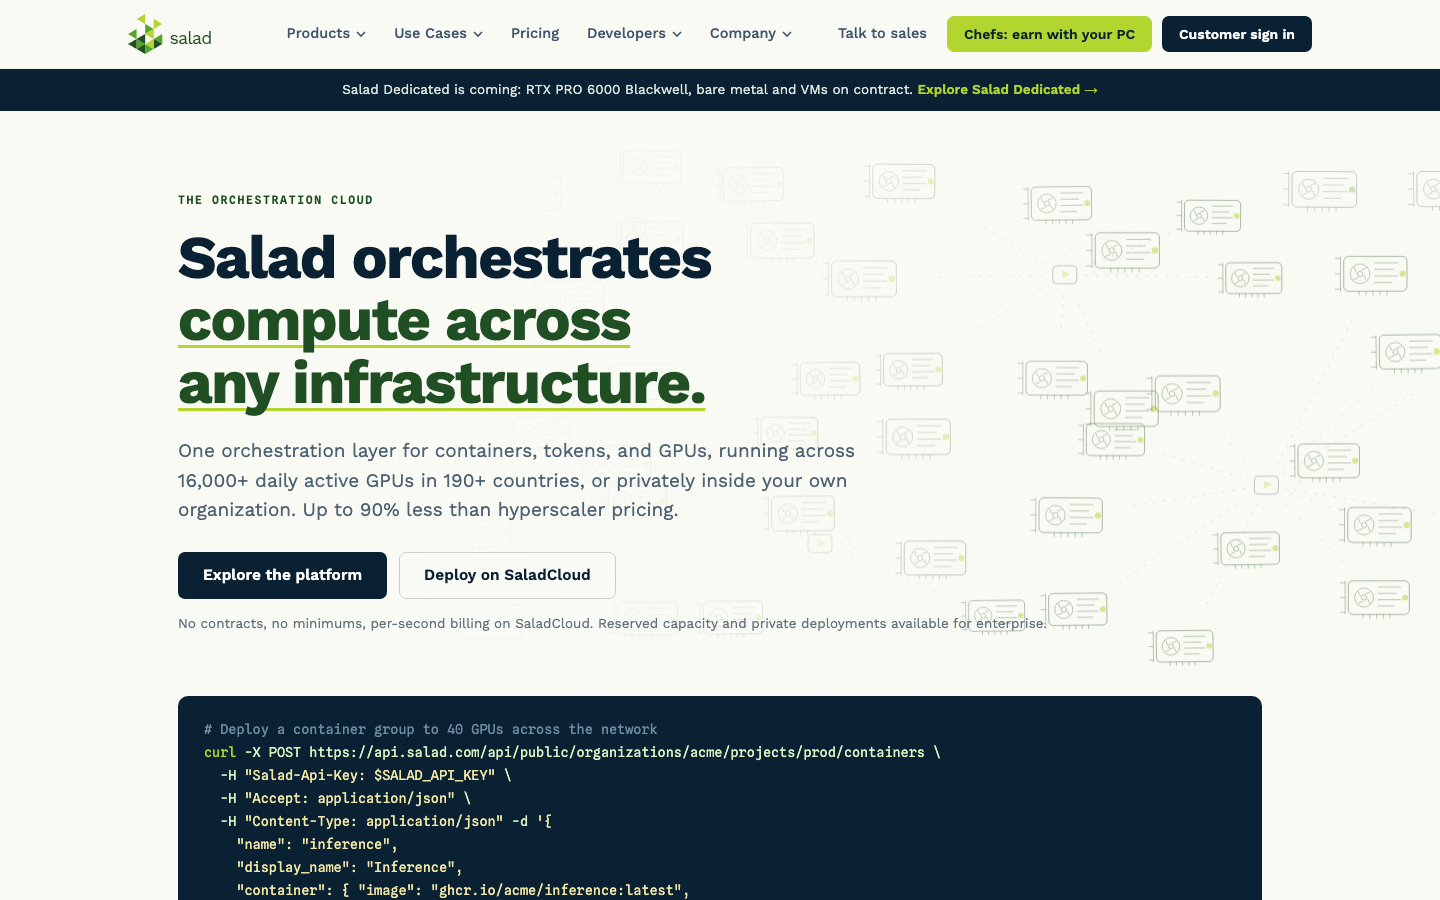
SaladCloud pools idle consumer RTX GPUs around the world into one distributed compute network, scheduling Docker containers with its in-house container engine, billing by the second, and claiming on its site that it is up to 90% cheaper than hyperscale clouds. The current site wording is 16,000+ daily active GPUs across 190+ countries.
Core Capabilities
- Per-second billing: you pay only for the seconds an instance is running; allocation, image pulls and cold starts are free, and vCPU and memory are bundled with the card
- Four priority tiers: High / Medium / Low / Lowest(Batch) get cheaper step by step, with Lowest at roughly four tenths of High and older cards down to $0.015/GPU-hour
- Salad Container Engine: managed container orchestration — declare the image, GPU class and replica count, and nodes that drop offline are rescheduled automatically
- AI Gateway: an OpenAI-compatible endpoint with 4 Qwen models and a 262,144 context, input from $0.06 per 1 million tokens, still in beta
- Transcription API: billed per audio hour, from $0.20 and down to $0.08 at volume, with the company citing 95.1% accuracy
- Scale-up options: Salad Dedicated reserves RTX PRO 6000 Blackwell, and Private Cloud licenses deployments on your own hardware
Best Use Cases Batch image generation with ComfyUI / SDXL / FLUX, retryable transcoding and embedding batches, queue-driven stateless inference, transcription teams running tens of thousands of hours a month, and developers who want to point Cline or Aider at a cheap Qwen endpoint.
Unique Advantages At this price point it has almost no rival: an RTX 4090 at the Lowest tier costs $0.160/GPU-hour, clearly below community clouds in third-party comparisons. It does not sell H100s and does not promise an SLA — what you get in exchange is a floor price close to the cost of electricity.
Editorial Verdict The first choice for cost-sensitive teams with retryable workloads; Civitai and Blend are living examples. But you have to accept higher cold starts and instances that can disappear at any moment, so idempotent retries and checkpoints are on you. Start with a small top-up and one small container group to validate, then talk about long runs and volume discounts.
Pricing
Subscription$0.015/GPU-hour (Lowest tier, older GPU classes)Not preempted by other workloads, but nodes are still rescheduled if they lose power or network; RTX 4090 is $0.440 and RTX 5060 8GB is $0.115
Roughly four tenths of the High tier, cheapest and most easily interrupted, suited to retryable batch work; RTX 5090 $0.250, RTX 4090 $0.160, older GPU classes as low as $0.015
1vCPU+1GB is about $0.006/hr; it can only run on the Lowest tier, and any group that needs a GPU can preempt it
Early access/beta, OpenAI-compatible endpoint, only 4 Qwen models and a 262,144 context; output $0.23–$1.90, the flat monthly fee must be requested and the amount is not public
Down to $0.08 at volume (Lite tier), billed per 0.01 audio hours, failed jobs are not charged
Contract reservation of RTX PRO 6000 Blackwell 96GB, quoted by GPU count and term; Private Cloud is billed per deployment license
Additional notes
Everything is billed per second, counting only the seconds an instance is in the running state; allocation, image pulls and cold starts are free, and vCPU and memory come bundled with the GPU. GPUs come in four priority tiers — High / Medium / Low / Lowest(Batch); lower tiers are cheaper but more easily preempted by higher-priority work: Medium and Low are only guaranteed for as little as about 30 minutes before preemption, Lowest has no guarantee at all, and the High tier is not preempted by other workloads although nodes are still rescheduled if they lose power or network. Prices float with supply and demand; long runs, more than 100 GPUs and committed spend are negotiable; AI Gateway is currently in Early access. No free trial and no monthly subscription tier.
FAQ
User reviews
User Reviews
No reviews yet
No one has reviewed this tool yet