Runware
Unified platform for multimodal inference and GPU compute
Tool details
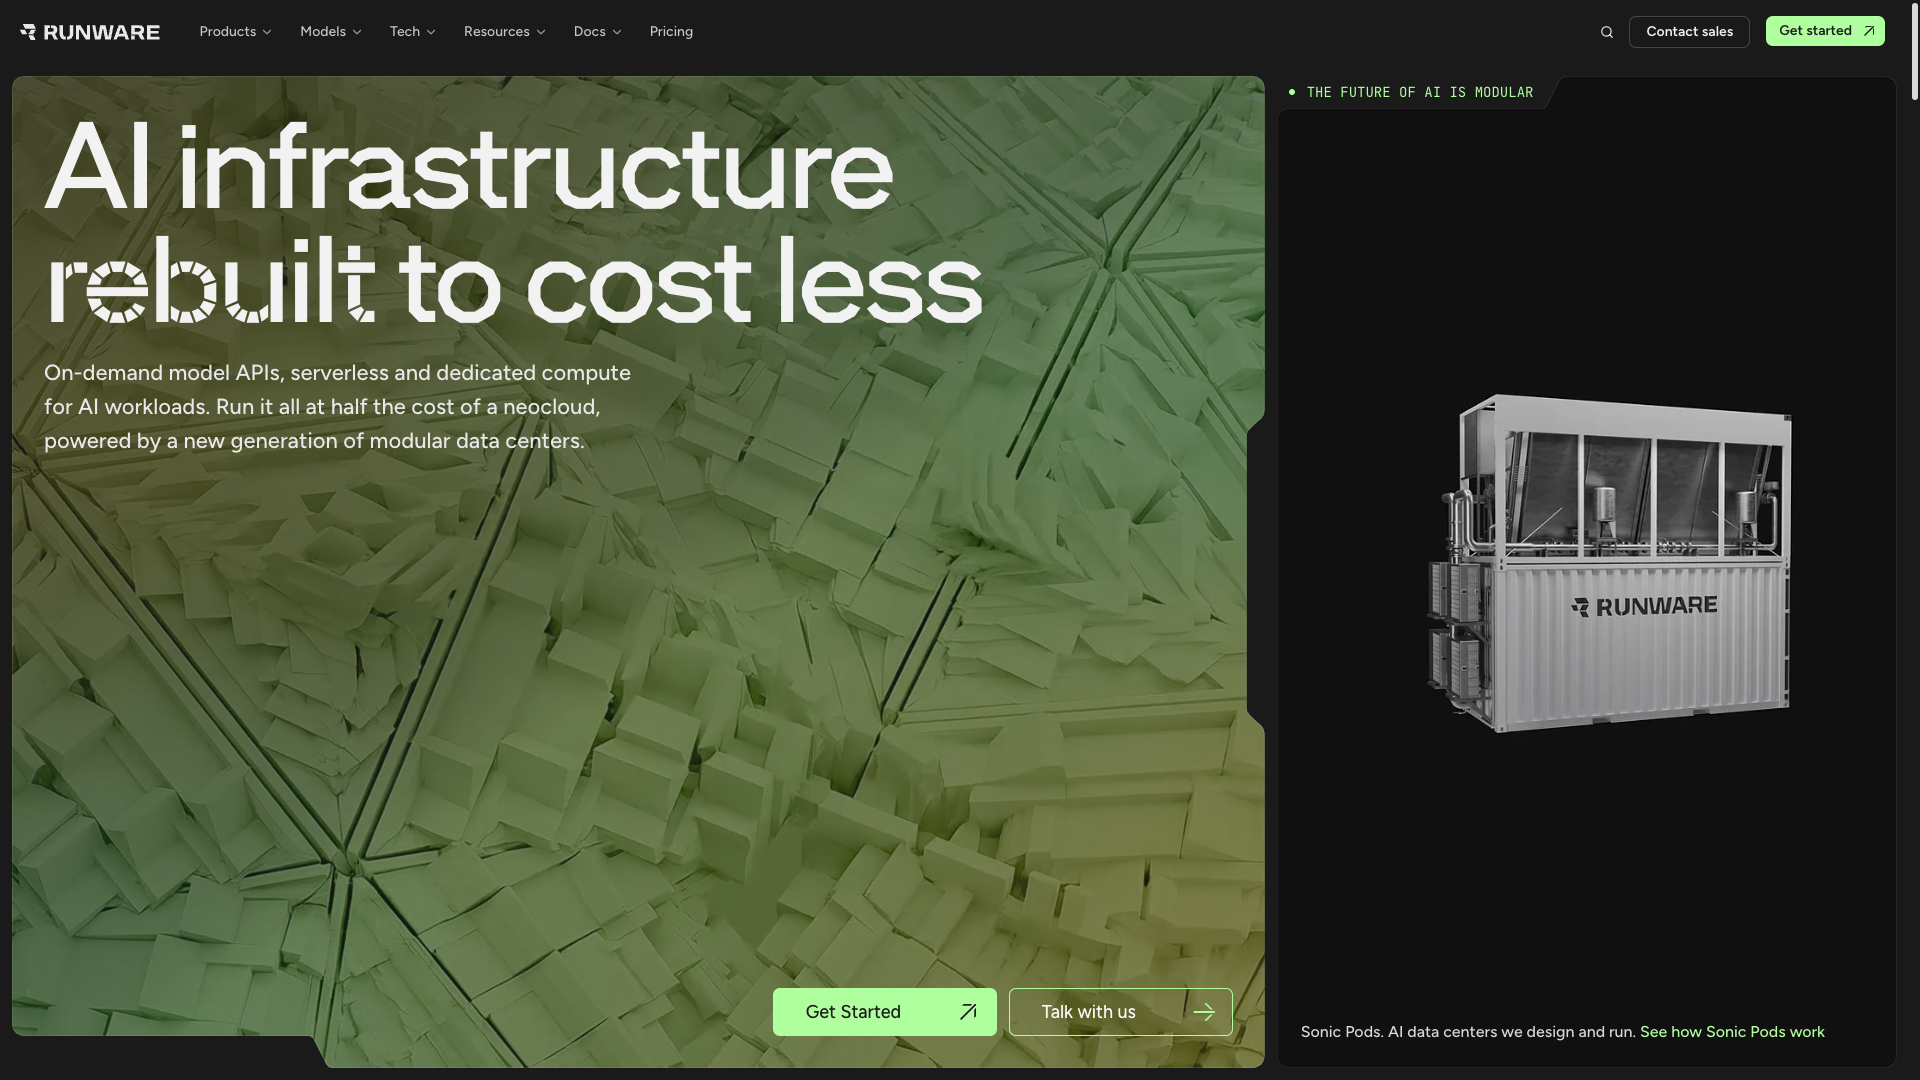
Runware turns model serving into a layer of infrastructure: one endpoint reaches 400,000 models, with image, video, audio, 3D and language sharing the same auth and billing, so switching models is just a string change. It is built for engineering teams that want generation inside their product without running their own GPU fleet.
Core capabilities
- Unified endpoint: all five modalities share one endpoint; LoRA and ControlNet stack per request, and swapping models does not change your integration.
- Serverless hosting: bring a container and weights, scale to zero, get multi-tenant isolation and per-second GPU billing.
- Reserved capacity: H100 from $2.45 and RTX 4090 from $0.50 per GPU hour, trading a 1-24 month commitment for a lower rate.
- Sonic Pods: a 20-foot container holds 1MW, sited next to renewable power; the company claims up to 10x lower delivered cost.
- Broad catalogue: 400,000+ models to search, 300+ of them with public rates so a build can be priced before committing.
- Agent tooling: MCP server, CLI, skills, Playground and LoRA training are all in place for automated pipelines.
Where it fits Batch image generation, short-video and ad creative production, audio and dubbing pipelines, 3D asset pre-generation, and SaaS products that bring their own models. Best when someone on the team writes code and still has to answer for the monthly GPU bill.
Why it stands out Most rivals either resell GPUs or cover a single modality. Runware builds its own engine and its own data centres, bills by the second with scale-to-zero, and keeps every modality behind one API, which together undercuts pure resale on cost.
Editor's take This is not an off-the-shelf consumer tool but an inference base for engineering teams. The real savings sit in reserved capacity and scale-to-zero, which assumes predictable load. The $2 credit only proves the plumbing, so run pay-as-you-go for a month before negotiating a commitment.
Pricing
Subscription$1.10/GPU-hour (RTX 4090 on demand)$2 in trial credit for business-email signupsImages per image, video per clip, LLMs per input and output token; 300+ models publish rates
24 GB of memory, billed by the second, for smaller image and video jobs
96 GB of GDDR7, the main tier for diffusion and multimodal inference
80 GB of HBM3, aimed at LLM inference that fits in 80 GB
Blackwell inference for large models; B300 carries 280 GB of HBM3e
1 to 24 month terms; usage above the reservation falls back to on-demand rates
A physical core equals about 2 vCPU, used for pre- and post-processing
Rack-scale Blackwell Ultra, scoped with the engineering team
Additional notes
Reserved rates are negotiated, and published on-demand rates drift with the market; community models rarely publish rates, so estimate them in the model page or Playground.
FAQ
User reviews
User Reviews
No reviews yet
No one has reviewed this tool yet