DeepInfra
Open-model inference cloud billed per token
Tool details
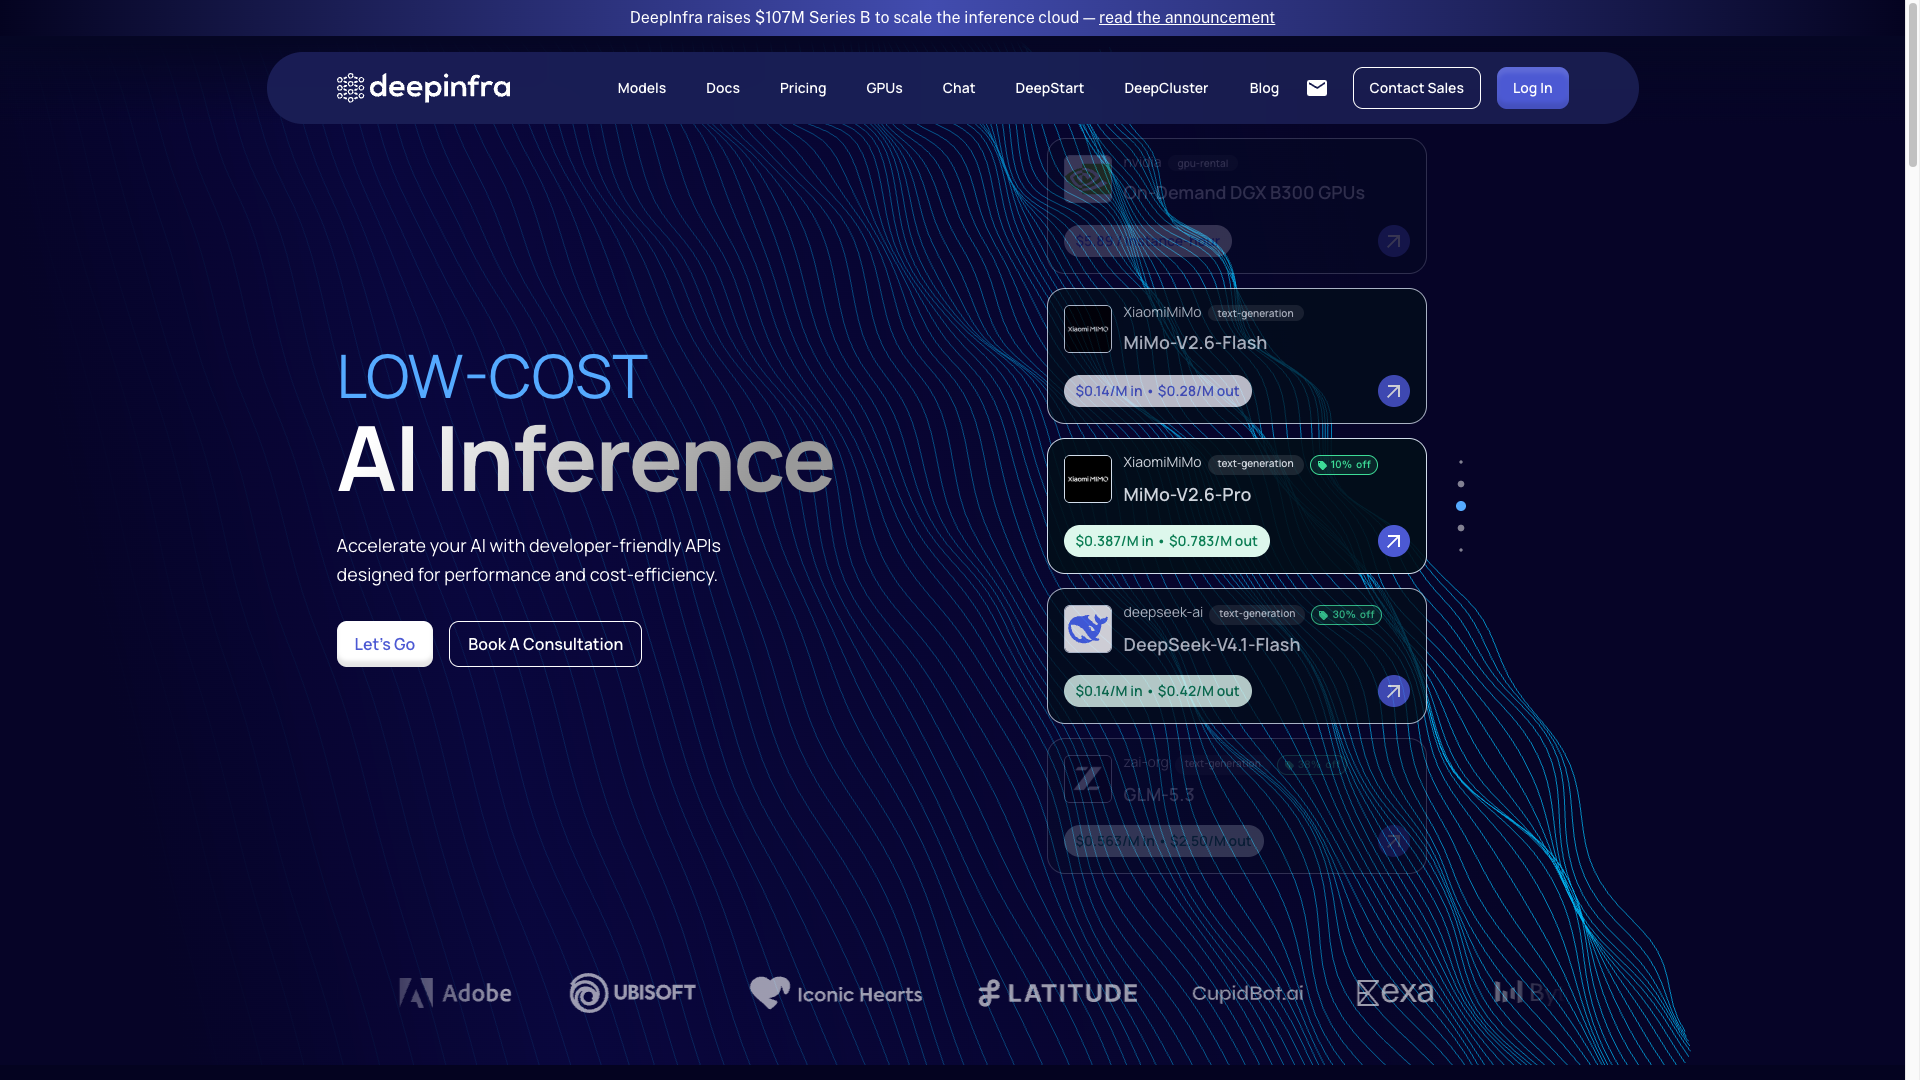
DeepInfra does one thing: it serves open models fast and cheap. Its own GPUs, its own data centres and its own inference stack sit behind OpenAI-compatible endpoints for DeepSeek, Qwen, Llama, Kimi and Flux, so migrating often means changing a base_url. The audience is engineering teams putting models into production systems.
Core capabilities
- OpenAI-compatible API: 150+ open models share one calling convention, so existing SDKs and clients move over with almost no rework.
- Token pricing: mainstream models sit at the low end, and inputs that hit the cache cost 0.2 to 0.5 of the normal rate.
- Three service tiers: Standard at base price, Priority at 1.5x for a faster first token, Flex at 0.8x for non-production work.
- Dedicated GPUs: A100 through B300 billed by the minute and settled weekly, for models that need more than 80 GB or an exclusive card.
- DeepCluster: 256 to 5,000 GPUs fully managed, from design and procurement through deployment and 7x24 operations.
- Enterprise defaults: zero data retention, SOC 2 and ISO 27001, with compute in eight self-owned US data centres.
Where it fits High-volume token traffic inside agent products, SaaS that needs private model hosting, batch image and speech inference, and heavy teams replacing public cloud with their own cluster. For plain chat, the web app is enough.
Why it stands out Its pricing is not subsidised; it comes from owning data centres and the inference stack. A cluster on a three-year term can land below 3 US dollars per GPU hour, roughly half of public cloud by the company's own count. The team also ran the backend behind imo, so scale operations is familiar ground.
Editor's take On open-model inference, DeepInfra is hard to beat on both price and stability, and the 107 million dollar Series B in 2026-05, with NVIDIA joining, adds supply certainty. The gap is that there is no general free allowance, so individual developers pay to experiment, and the data centres sit in the US, which non-US traffic has to account for.
Pricing
Subscription$0.06/1M input tokens (DeepSeek-V4-Flash-0731)LLMs, embeddings and rerankers price input and output separately, with a further discount on cached input
Image, video and speech models mostly bill by execution time, so you pay for what you use
Requests jump ahead of standard traffic for a faster first token, where the model allows it
For non-production and async jobs, with slower responses and occasional unavailability
80 GB of memory, billed by the minute and settled weekly, for self-hosted inference
80 GB of HBM3 and 141 GB of HBM3e, for long context and larger models
180 GB and 270 GB of memory on the Blackwell platform
256 to 5,000 GPUs fully managed, including procurement, deployment and operations, on a 3 to 5 year contract
Additional notes
There is no general free allowance. DeepStart gives startups that raised between 250,000 and 10 million US dollars about 50 billion free tokens. DeepCluster pricing varies with configuration and term.
FAQ
User reviews
User Reviews
No reviews yet
No one has reviewed this tool yet