Runcrate
An aggregation layer for buying model calls and GPU compute from one balance
Tool details
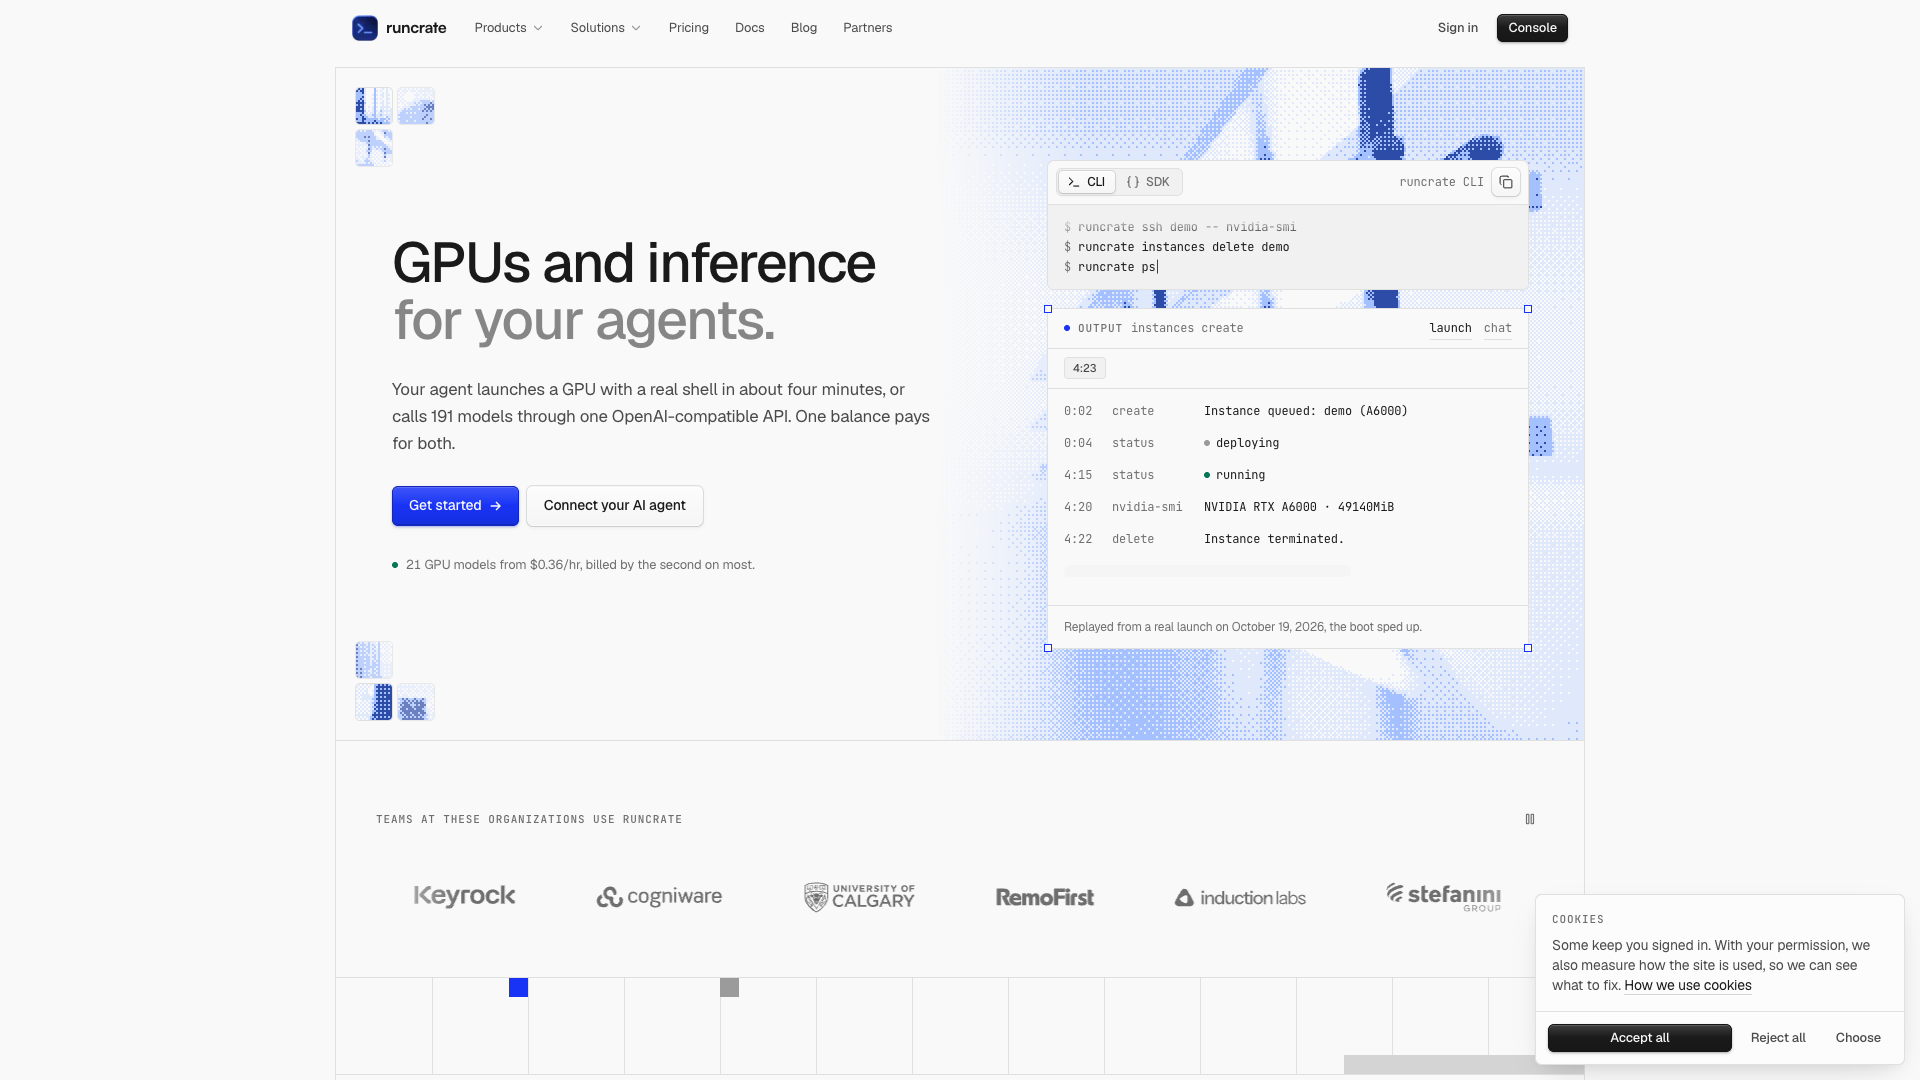
Runcrate is an AI cloud platform from Aeonmind LLC that puts an OpenAI-compatible inference API and on-demand GPUs behind a single prepaid balance. In testing the API returned 191 models, and most of the 20 GPU tiers bill per second; it builds its own control plane while compute is supplied by partner data centers, which makes it essentially an aggregation and orchestration layer.
Core capabilities
- OpenAI-compatible inference: point
base_urlat it and migrate, plus an Anthropic Messages endpoint - On-demand GPUs: 20 GPU tiers, mostly billed per second with no charge during boot, with root shell and SSH, Jupyter and VS Code
- MCP native: OAuth dynamic registration needs no key, so an agent can start machines and run SSH commands on its own
- Crates images: prebuilt Devbox, Finetune and Inference images, the last shipping vLLM or SGLang
- Reserved clusters: when B200, GB200, GB300 and MI300X are out of stock, requests move to multi-node sealed bidding
- Cost guardrails: Jobs require a maximum runtime of 1 minute to 24 hours, with idle stop and a monthly budget
Where it fits Independent developers and small teams, engineers who write and run training scripts with coding agents, researchers doing fine-tuning and short experiments, and multimodal teams that want images, video and audio behind one endpoint. It is not a fit for procurement that needs enterprise SLAs or fixed quotes.
What sets it apart The difference from RunPod and Vast.ai is not the lowest single-GPU price but buying tokens and GPUs from one balance, plus keyless agent access; per-second billing and published startup-latency percentiles are also unusually candid. The trade-off is direct: supply is aggregated, the same model can vary several-fold in price, and a listed price does not mean stock is available.
Editorial verdict The capability is real and the pricing is candid enough for four stars. Points come off for credibility: the terms explicitly do not guarantee availability, refunds are "at our discretion", third-party reputation is close to zero (no entries on G2, Capterra or Trustpilot), and a team of 5 is supporting a catalog of 191 models and 20 GPU tiers. Best suited to cost-sensitive teams willing to set their own limits and checkpoints.
Pricing
Freemium$0 (free allowance for 5 open-source models, GitHub account at least 30 days old)The free allowance is not a permanent free tier: it requires a GitHub account at least 30 days old, is capped both per session and per week (resetting on Monday), and overage bills at half price on shared capacity; the site has no invite codes and no queueing mechanism.Officially 5 open-source models can be called free of charge, with a GitHub account at least 30 days old; the allowance is capped both per session and per week (resetting on Monday), and overage bills at half price on shared capacity
191 models verified callable, across 7 billing units (per 1M tokens, per image, per second, per 1K characters and more); compatible with the OpenAI and Anthropic SDKs
20 GPU tiers in stock, from V100 32GB at $0.36 up to B300 at $9.74; most bill per second with no charge during boot, plus about a 30-second teardown buffer after deletion
When B200, GB200, GB300 and MI300X are out of stock on demand, requests go through multi-node sealed bidding, with quotes shown side by side and matched manually
10–10,000 GB persistent volumes mounted at /workspace, prepaid weekly, with unused days refunded on early deletion
Additional notes
Prices are taken from the raw HTML on /pricing and /inference/pricing; GPU prices move with upstream supply (H100 has appeared at $3.25, $3.38, $3.55 and $3.69, and this article uses $3.55). The 20 tiers are the models currently in stock; the machine-readable feed has 24 entries, with another 4 priced but unavailable; the terms still say per-hour billing, which conflicts with the per-second billing used on most of the page. The vendor also cites 200+ and 223 models; this article uses the reproducible 191. The free allowance is disclosed only on /inference/free and is not mentioned on the pricing page at all. It is an aggregation layer: the terms state that instances and models may run on partner infrastructure, so the same model can vary several-fold in price and price inversions occur. Payments go directly through Stripe, with USDC (≥$100) and bank transfer (≥$2,500) also supported; refunds are at our discretion under the terms.
FAQ
User reviews
User Reviews
No reviews yet
No one has reviewed this tool yet