
Kimi K2.7 Code: 3 Design Drafts in 8 Minutes, 3 Bugs Fixed in 20
Kimi K2.7 Code supports parallel agents (swarm), forces thinking on, and its coding ability approaches GPT-5.5 and Opus 4.8
Kimi K2.7 Code: 3 Design Drafts in 8 Minutes, 3 Bugs Fixed in 20
Kimi K2.7 Code supports parallel agents (swarm), forces thinking on, and its coding ability approaches GPT-5.5 and Opus 4.8
Kimi K2.7 Code is the new-generation coding model released and open-sourced by Moonshot AI, now switched on across Kimi Code in full. Its defining traits are speed, low cost, and support for parallel agents (swarm), with some coding benchmarks approaching GPT-5.5 and Opus 4.8. A high-speed version launches next Monday, raising output speed 5-6x.
Core Features
Parallel Agents (Swarm)
K2.7 Code's standout ability is proactively spinning up parallel agents. Give it a design task and it automatically launches multiple agents working at the same time, each producing a complete draft in a different style.
Hands-on example: given a single design Skill instruction, K2.7 Code launched three parallel agents within 8 minutes, each producing a complete HTML animation mock in a different design school, and automatically took screenshots for selection.
Forced Thinking Mode
The model forces thinking on (similar to Claude Fable 5's approach); turning it off makes the API throw an error outright. The team specifically tuned the overthinking problem, using 30% fewer thinking tokens than the previous generation. The thinking process is displayed throughout, which greatly reduces the wait-time anxiety.
Automated Debugging
In testing, K2.7 Code was asked to fix three bugs in FanBox (a product built with Claude Fable 5). The full rundown:
- When special bytes made the file-reading tool refuse to read a file, it switched to Python binary inspection on its own
- When a local proxy hijacking localhost caused a 502, it investigated processes and environment variables by itself and added parameters to route around it
- After fixing, it automatically ran syntax checks and built three edge-case test pages to verify the results
Three bugs, fixed in 20 minutes, without a single line of code typed by hand.
Performance and Pricing
| Item | Standard | High-speed (launches next Monday) |
|---|---|---|
| Output speed | Standard | 180 token/s (260 on short context) |
| API input price | 6.5 CNY per million tokens | - |
| API output price | 27 CNY per million tokens | - |
| Cache hit | 1.3 CNY per million tokens | - |
| Price multiplier | 1x | 2x (6x speed) |
Once the high-speed version launches, the 8-minute animation design can shrink to about 2 minutes, and the 20-minute bug fix to about 4 minutes.
How to Use It
Via the Kimi Code CLI
- Visit kimi.com/code
- Membership starts at 49 CNY, with quota counted on a rolling 5-hour window
- Supports custom Skills and can reuse an existing skills directory directly
Via the API
- Input: 6.5 CNY per million tokens
- Output: 27 CNY per million tokens
- Cache hit: 1.3 CNY per million tokens
- High-speed version: 2x the price, 6x the speed
Use Cases
- Rapid prototype design: parallel agents produce multiple versions at once
- Bug fixing and maintenance: a closed loop of independent investigation, fixing, and verification
- HTML animations / interactive pages: design expressiveness beyond expectations
- Skill-driven workflows: design the loop once, agents run it over and over
Suggested Division of Labor
| Model | Profile | Best for |
|---|---|---|
| Claude Fable 5 / Opus 4.8 | Slow, precise, expensive | Breaking new ground from zero to one, design loops |
| Kimi K2.7 Code | Fast, steady, cheap | Running nonstop inside the loop, day and night |
| GLM-5.2 | Open source, locally deployable | Data-sensitive scenarios, the top pick in China |
💡 Tip: Kimi Code recognizes Claude Code's skills directory directly, no reinstall needed. If you can't remember a Skill's name, type
/skilland pick from the dropdown list.
Sources: hands-on testing by Huashu, Kimi official announcements
Related articles
A Practical Guide to Saving Tokens in Claude Code
Master the prompt caching mechanism, session management strategies, and six core rules to make your Claude Code quota last longer and spend better.

Hermes Agent: The Complete Tutorial from Installation to WeChat Integration
The open-source AI agent Hermes Agent supports 13 large models and natively connects to WeChat, Feishu, and DingTalk; get started for $3.99, with the full installation and WeChat setup process included.
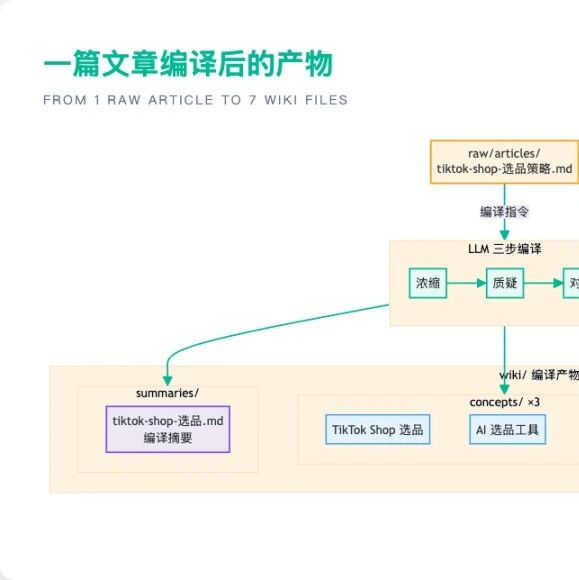
Build a Self-Evolving Knowledge Base with Claude Code + Obsidian
An improved three-step compilation method based on Karpathy's LLM Wiki methodology that turns Obsidian notes from an information dump into a continuously evolving knowledge asset, with the complete directory structure and prompts included.
Deep Researcher Agent: For 0.5 Yuan a Day, Let AI Run Your Deep Learning Experiments
The open-source Deep Researcher Agent framework runs deep learning experiments automatically 7x24 through an autonomous loop, needs no LLM API, supports mobile monitoring, and costs only 0.5 yuan a day.
Nuwa Skill: Distilling How the Great Minds Think into Callable AI Skills
The open-source project Nuwa Skill automatically researches a person's public materials, extracts their thinking and decision-making patterns, and generates a Skill file you can call again and again; 17 figures have already been distilled, completely free under the MIT license.