
Claude Fable 5 and Mythos 5 Launch
Anthropic has launched its Mythos-tier flagship models: Fable 5 is open to all users and scores 80.3% on the software engineering benchmark SWE-bench Pro, with input priced at $10 per million tokens.
Claude Fable 5 and Mythos 5 Launch
Anthropic has launched its Mythos-tier flagship models: Fable 5 is open to all users and scores 80.3% on the software engineering benchmark SWE-bench Pro, with input priced at $10 per million tokens.
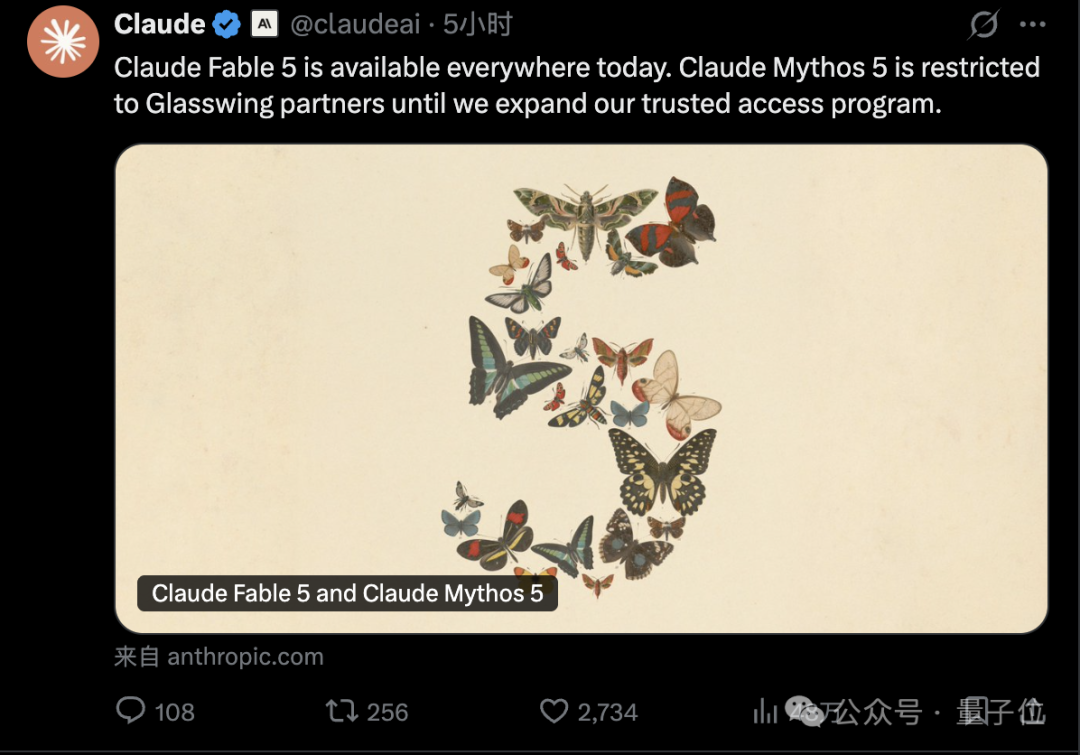
Anthropic has released two Mythos-tier flagship models at once: Claude Fable 5 is open to all users, while Claude Mythos 5 is limited to trusted partners. Both are built on the same underlying model; the difference is that Fable 5 ships with built-in safety classifiers that automatically downgrade to Opus 4.8 when requests touch cybersecurity, biochemistry, or model distillation.
What Is Fable 5
Fable 5 is the strongest model Anthropic has ever publicly released. It surpasses its predecessor across software engineering, knowledge work, visual reasoning, long-context memory, and scientific research. The name Fable comes from the Latin fabula ("story"), related to Mythos ("myth") — the same underlying model, with the public edition called "fable" and the full edition called "myth."
One core advantage of Fable 5: the longer and more complex the task, the wider its lead over other models grows. It holds focus across million-token, long-running tasks and improves its output using its own notes.
Core Capabilities at a Glance
Software engineering: SWE-bench Pro 80.3%
- SWE-bench Pro score of 80.3%, far ahead of GPT-5.5's 58.6% and Gemini 3.1 Pro's 54.2%
- FrontierCode Diamond score of 29.3% (GPT-5.5 manages just 5.7%), and it hits that top score at medium reasoning effort
- Stripe used Fable 5 to migrate an entire codebase of 50 million lines of Ruby in a single day (a job that would take humans more than two months)
Visual reasoning: beating Pokémon with pure vision
Previous Claude models needed elaborate tooling scaffolds to play Pokémon FireRed. Fable 5 beat the entire game from scratch on screenshots alone, without any map cheats or extra information.
On GDPpdf (a visual document reasoning benchmark), Fable 5 scored 29.8%, ahead of Opus 4.8 (22.5%) and GPT-5.5 (24.9%).
Long context and memory
Fable 5 holds focus across million-token, long-horizon tasks. In Slay the Spire playtests, once persistent file-based memory was attached, Fable 5's performance gain was 3x that of Opus 4.8. That means the model's ability to "learn from its own experience" has stepped up to a new level.
Scientific research (Mythos 5)
- Protein design: produced 9 candidate designs for 14 disease targets, spanning immune, neurodegenerative, and muscle diseases
- Genomics: autonomously collected data on 138 species and millions of cells, then trained a model 100x smaller that outperforms results published in Science
Pricing and Availability
| Item | Details |
|---|---|
| API name | claude-fable-5 |
| Input price | $10 / million tokens |
| Output price | $50 / million tokens |
| Free window | From now through June 22, free for Pro/Max/Team/Enterprise subscribers |
| From June 23 | Removed from subscription plans; requires usage credits |
That's twice the price of Opus 4.8, but less than half of Mythos Preview.
Tip: Finish your heaviest tasks before June 22. After that, Fable 5 will be removed from subscription plans and available only through API credits. Anthropic says it will be readmitted to subscriptions when capacity allows.
Safety Mechanisms
Fable 5 sits behind a set of independent classifiers watching for three risk categories: cybersecurity, biochemistry, and model distillation. On a trigger, replies automatically downgrade to Opus 4.8. Official figures show over 95% of conversations never trip the downgrade.
Note: the classifiers are currently tuned conservatively, so legitimate code review and security-hardening requests can get caught in the crossfire. Anthropic says it will work on reducing the false-positive rate.
Money-Saving Tips for Fable 5
Fable 5's list price is double Opus's, but the real cost comes from how much it "thinks and how long it runs." Practical advice:
- Check the thinking level: switching to Fable from another model doesn't auto-reset the thinking setting — set it manually to what the task actually needs
- Compact sessions proactively: at each milestone in a large project, compact once (e.g.
/compact) and don't let the session grow endlessly - Scope tasks with a cheaper model first: before launching a large agentic run, use a cheaper model to pin down the task's scope and cut the number of rounds Fable spends feeling its way
- Default to Sonnet/Opus: everyday Q&A and simple code edits go to lower-tier models; switch to Fable only for genuinely complex multi-step tasks
- Watch your usage rhythm: under heavy use the 5-hour window can burn down in a few dozen minutes — schedule your most token-hungry tasks right after the window refreshes
Core principle: cheap models handle the everyday and the prep work; Fable handles the parts that truly demand a ceiling-level mind.
How to Get Started
- Head to claude.ai and pick Fable 5 in the model selector
- API users can call
claude-fable-5directly - Claude Code users are supported as well
A good first move: test it on the most complex task you have at hand and get a direct feel for the gap versus Opus 4.8.